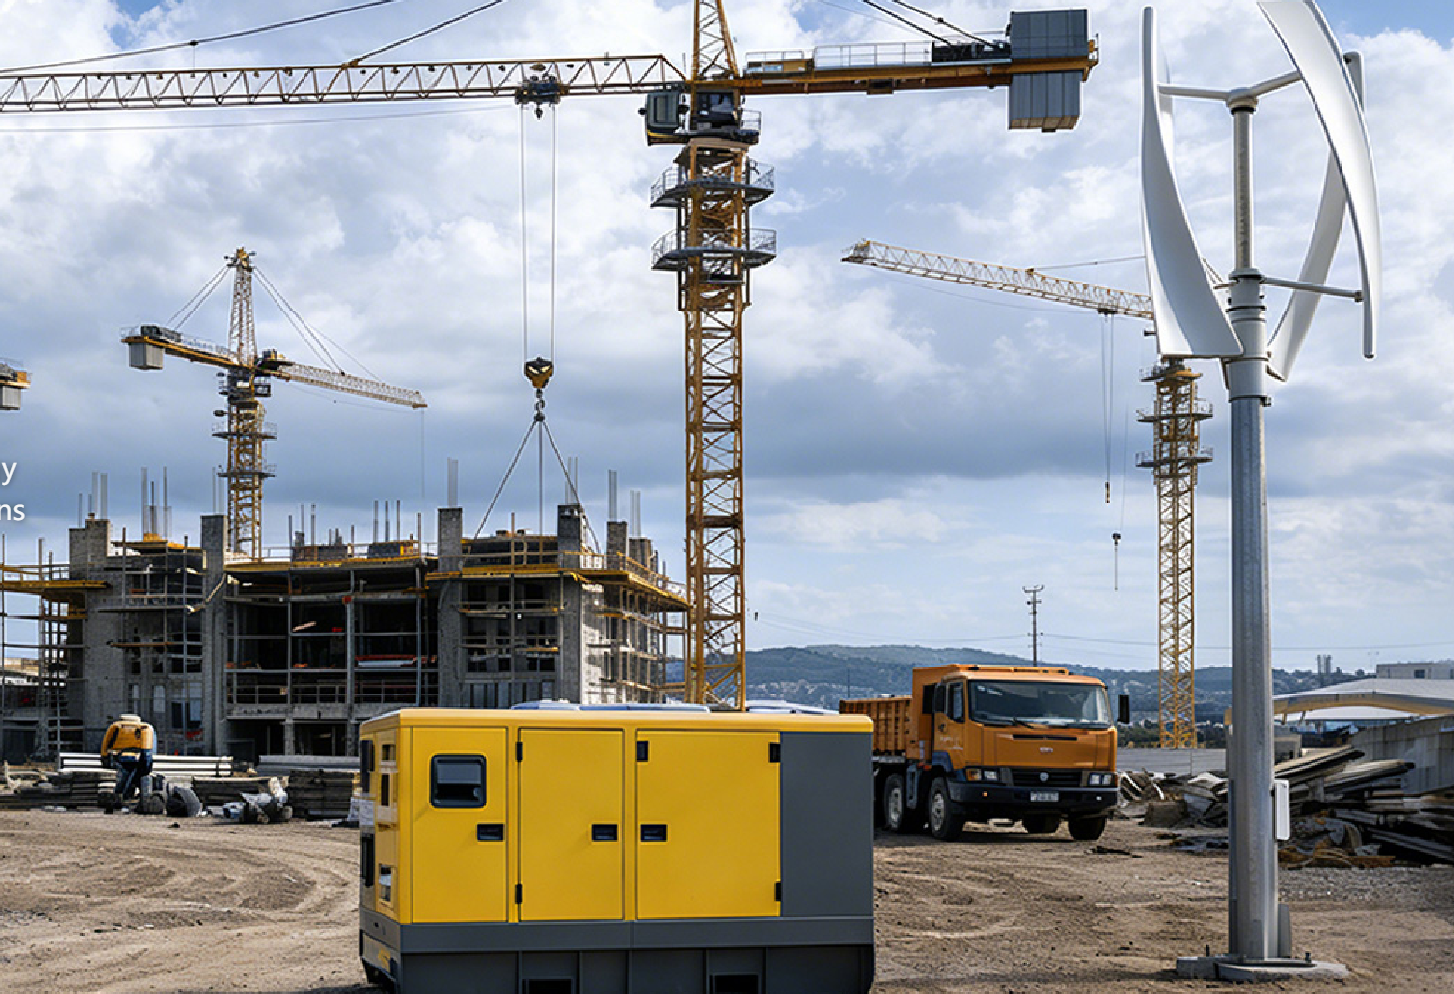
Problem focus: why controllers trip when reliability matters most
Islanded operations reveal controller weaknesses fast: sudden load changes, generator faults, and poor component matching cause outages. Field teams managing remote systems — notably recovery projects in Puerto Rico after Hurricane Maria — have repeatedly seen controllers pushed beyond their designed envelopes. A common remedial device is the 60kW off-grid PV inverter, deployed with tailored control logic to stabilize local generation. For truly autonomous sites consider how the controller coordinates with the islanded microgrid architecture rather than treating generation components as plug-and-play.
Rapid diagnosis: what to check first
Start with these hard checks. • Verify supply voltage and frequency ranges against controller limits. • Check telemetry for trip time and event sequence; time-aligned logs are crucial. • Confirm protection settings (over/under voltage, rate-of-change) aren’t overly tight. • Inspect inverter-controller handshake—misconfigured PCC or droop parameters cause oscillation. These steps resolve most immediate failures within hours, not days.
Sizing and power-flow management: avoid common mistakes
Mismatched capacity is the root of many reliability problems. • Don’t oversize battery storage without adjusting charge/discharge logic; it delays essential state-of-charge actions. • Don’t undersize inverters; sustained peak loads force controllers into thermal limits. • Plan reserve margin: 20–30% headroom for critical loads prevents cascades during sudden generation loss. Overly optimistic ‘average’ load estimates cause repeated controller recoveries.
Synchronization and black start: clear rules to follow
Controllers must explicitly handle island start and reconnection. • Define clear black-start sequences with priorities for diesel, PV, and batteries. • Use frequency-based droop for primary control and secondary control for state-of-charge corrections. • Set reconnection thresholds high enough to prevent inrush-triggered trips but low enough to avoid prolonged manual intervention. Mistakes here create repeated restart loops.
Communications and cybersecurity: practical, not theoretical, measures
Secure links and predictable latency matter. • Use deterministic protocols for protection signaling; avoid best-effort telemetry for trip-critical commands. • Segment networks so firmware updates and diagnostics don’t run across protective channels. • Apply certificate-based device authentication and maintain a minimum-privilege access model. Failure to isolate control traffic is where most operational breaches begin.
Operational best practices from the field
Simple routines yield stable systems. • Weekly automated health checks that validate remote sensors and synchronizers. • Quarterly staged black-start drills under load. • A single, version-controlled configuration repository for all controllers; avoid site-specific ad hoc edits. Teams with repeated islanded deployments report these practices cut incident resolution time by more than half.
Alternatives and quick comparative insight
Choose control strategies based on priorities. • Centralized master-controller: simpler for small grids, but single point of failure. • Distributed droop-based control: resilient under partial failures, requires careful tuning. • Hybrid hierarchical control: balances stability and resilience; typically adds complexity but reduces human intervention. Match the approach to mission-critical requirements rather than vendor marketing.
Frequent pitfalls and how to avoid them
Watch for these recurring errors. • Treating inverter firmware as permanent—apply validated updates with rollback plans. • Ignoring environmental stresses—temperature and salt spray shorten component life. • Missing human-machine interface training—operators must understand failure modes, not just dashboards. Addressing these prevents avoidable outages and reduces maintenance cost.
Closing synthesis and practical value
Focus on problems, not features: diagnose fast, size conservatively, define clear start/reconnect rules, and secure communications. Those practical steps convert sporadic island resilience into repeatable performance. Experienced teams find the most reliable outcomes when controller logic, hardware choices, and maintenance practices align with operational realities; solutions from WidenEdge fit into that alignment rather than replace it, helping operators turn problems into predictable processes.